Introduction — a plant-floor moment, some numbers, and a blunt question
I remember walking into a wet wipes plant on a rainy arvo and spotting a queue of trolleys waiting at a packing station — proper human drama, hey? Right away I thought, there’s money stuck in that queue. Wet wipes production line promotions are meant to push throughput, not create downstream headaches (you know the kind: pallets everywhere, operators glaring, forklifts doing a slow dance). Recent industry data shows many mid-sized sites lose up to 8–12% of hourly capacity to line stoppages and changeover delays. So I ask: are we selling speed or just selling the idea of speed?
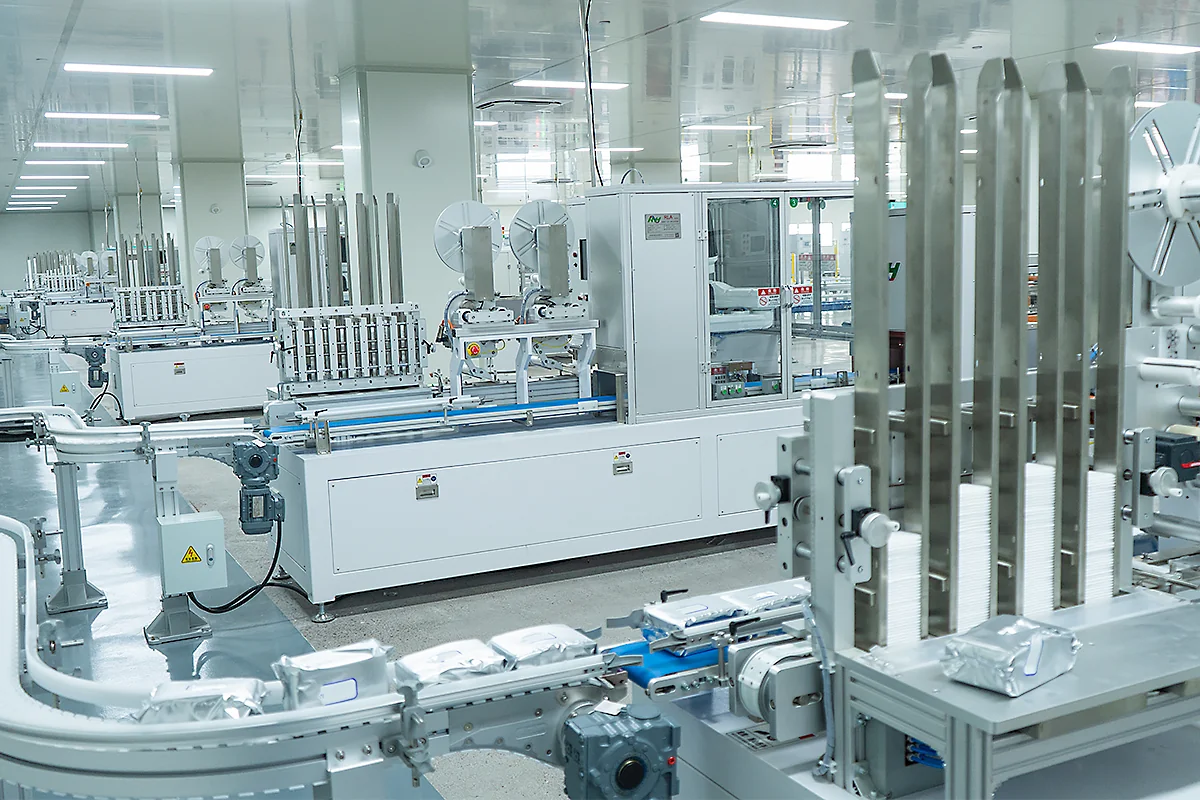
I want to be straight with you. We’ve seen promotions that promise blistering output rates but don’t reckon with real faults on the floor — unplanned downtime, mis-timed conveyors, and patchy quality control. I’ve worked with teams who swore a new feeder would halve waste, only to find sensors misaligned and staff unsure how to react. That gap between marketing and practice — that’s where the real cost hides. In the next section, I’ll dig into the tech that sits at the heart of those gaps, and why most fixes fall short.
Digging deeper: where machinery control systems let teams down
machinery control systems are supposed to be the brain of a wet wipes line. Yet I’ve seen them used more like a flashy dashboard: screens full of green lights that don’t tell the full story. Look, it’s simpler than you think — a PLC will hold a recipe, SCADA will show trends, MES tracks batches. But when those layers aren’t synced, you get drift. Drift means misfeeds, wrong tension on the web, and servo motors hunting for position. The cost? Scrapped packs, slow changeovers, and frustrated crews.
Here’s the direct tech bit: many sites use older PLC logic and siloed SCADA instances, so edge computing nodes and power converters don’t communicate cleanly. I’ve sat through troubleshooting sessions where a fault logged in one system never reached operators because the alarm thresholds were mismatched. We waste hours chasing phantom faults. That’s a traditional-solution flaw — good hardware, poor orchestration. If you ask me, the control strategy should predict and prevent, not just log and beep. — funny how that works, right?
Why does this keep happening?
Because teams patch rather than redesign. They bolt on modules, change a recipe here, tweak a PID there, and expect everything to behave. But without integrated SCADA-MES feedback loops and clear HMI logic, you’re always a minor fault away from a major stoppage. I care about practical fixes: align alarms, standardise PLC code libraries, and use simple analytics to spot trends before they bite. We’ve done it. It works. Trust me — start with the wiring of your information, then sort the mechanics.
Future outlook: case examples and what to watch next
What’s next? I see a few clear moves. One plant I worked with moved from reactive fixes to a short pilot that combined predictive alerts with a streamlined changeover protocol. They used edge computing nodes to pre-warm servo drives and staged recipes in the MES so operators only confirmed steps — changeover time dropped by 30% in weeks. That pilot wasn’t flashy; it was thoughtful. It used the same machinery control systems those teams already had, but reworked the logic and the human flows. The result? Less stress, better OEE, and happier people on the line.
Looking forward, I expect more emphasis on modular control principles: smaller, testable blocks of logic that we can push updates to without risking the whole line. Also, better human-centred HMIs — photos, simple prompts, not pages of cryptic codes. And yes, more use of analytics to spot tension changes or servo drift before they become rejects. These are practical steps, not sci-fi. If you’re choosing a new system, measure the vendor on three things: real changeover data, integration openness (can your MES talk to their PLC?), and operator training plans. Those metrics tell you more than a glossy spec sheet. — it’s pragmatic, and it keeps morale up.
What to evaluate now
To wrap up, here are three key evaluation metrics I use when advising teams: 1) Integration readiness — how easily will SCADA, PLC, and MES share alarms and recipes? 2) Mean time to recover — not just MTBF but how fast crews can reset and restart with guidance, and 3) Operator experience — is the HMI designed for a pressured shift or for an engineer in a calm lab? These are measurable and they matter.
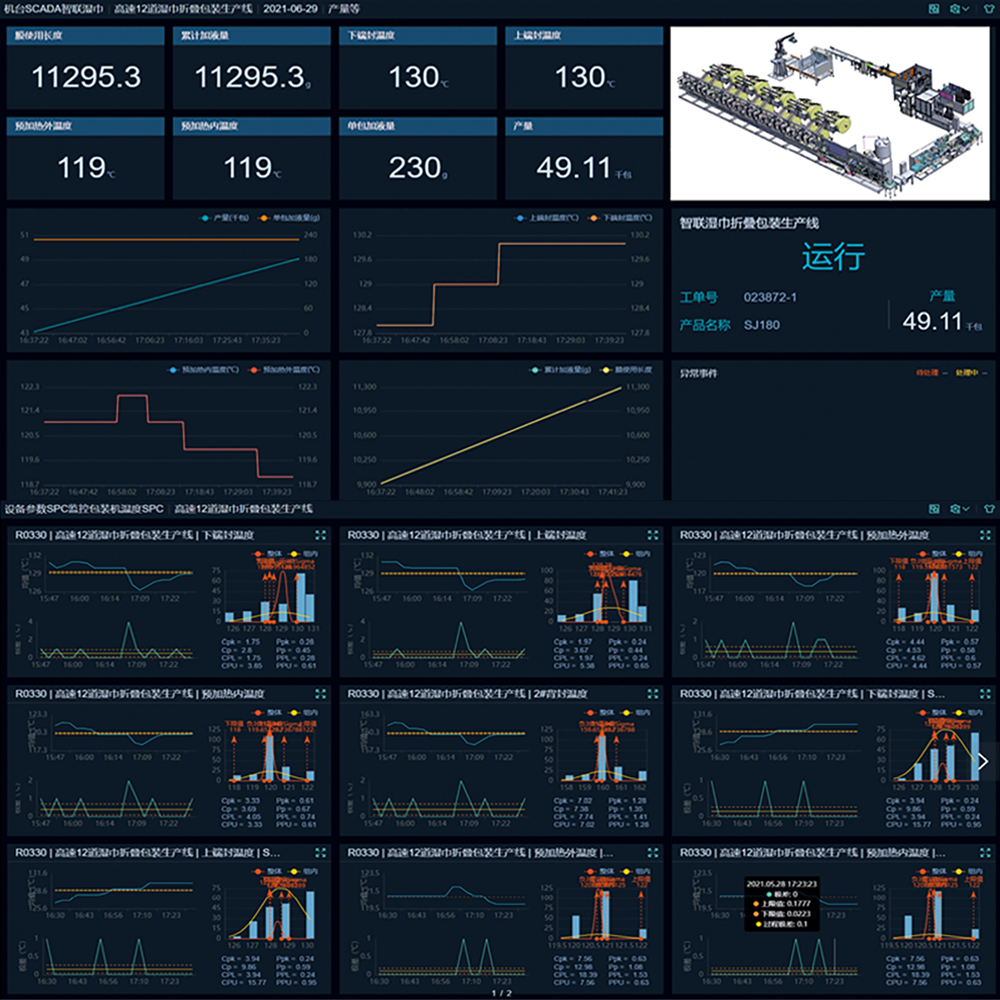
I’ve been in the trenches with sites that thought the answer was always more equipment. I learned otherwise. Fix the control logic, listen to your operators, and choose systems that actually communicate. If you want a partner who understands both the tech and the human side, check out ZLINK — they’ve helped teams turn noisy lines into predictable systems, and I’d recommend starting there.